- Summary:
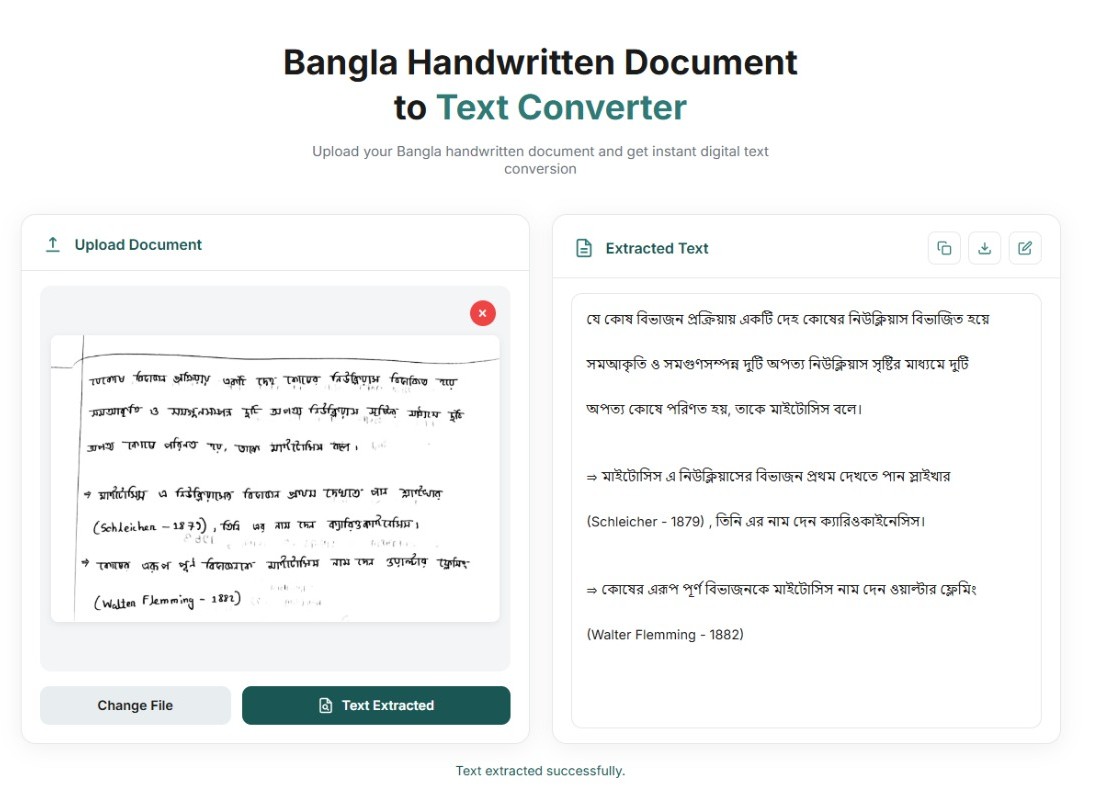
- This review paper presents a comprehensive overview of the development of Optical Character Recognition (OCR), Document Layout Analysis (DLA), Information Extraction (IE), and Key Information Extraction (KIE), with particular emphasis on Bangla and other low-resource languages. It reviews the evolution of OCR from traditional approaches to modern deep learning, transformer, vision-language, and large language model (LLM)-based methods, while examining their datasets, methodologies, evaluation metrics, and applications.
The survey also analyzes research trends and identifies major challenges, including limited annotated datasets, complex Bangla scripts, handwriting variability, document degradation, inconsistent evaluation, and limited cross-domain generalization. It further discusses practical applications in legal records, finance, healthcare, historical archives, and government services. Finally, the paper highlights emerging directions such as self-supervised learning, few-shot learning, synthetic data generation, multimodal models, and LLM-based OCR refinement, providing a clear view of the current research gaps and future opportunities for building more accurate, robust, and scalable document understanding systems for low-resource languages.
- Research Area:
- Optical Character Recognition (OCR), Document Layout Analysis (DLA), Large Language Model (LLM) and Intelligent Document Understanding.
- Status:
- Manuscript in Preparation